JoeJoe Cohen, BScCEO & Founder
15+ years researching health and science. Founded SelfHacked, LabTestAnalyzer and SelfDecode after resolving his own chronic health issues with a gene-based approach.
LinkedInWhat sets us apart
The reasons our partners give for choosing us over other providers.
01
With 40X whole genome sequencing, variants are measured directly rather than imputed. With genotyping, our published Selphi method imputes them from ~750,000 measured markers. Either way, our scores draw on far more of the genome than short published variant lists.
02
1,400+ polygenic risk models across heart, metabolic, cancer, neurological, autoimmune and mental-health traits, plus 1,500+ reports.
03
Our Orchestra method resolves local ancestry across 35 populations, so each person is compared with the right reference group.
04
Our ensemble models beat published alternatives on most of 30 conditions tested, across four ancestry groups and three cohorts.
05
PhDs and MDs build the models and write every report and recommendation. No report or recommendation is generated by AI.
06
Results combine with 4,000+ lab markers and 20,000+ interventions drawn from human trials, so reports lead to action.
Ancestry-informed
Our Orchestra method resolves local ancestry across 35 populations, so risk scores stay accurate beyond European ancestry.
Published in Nature Communications, 2025
Validated across African, East Asian, European and South Asian ancestry
1,400+ polygenic risk models, including 200 validated polygenic risk scores
The benchmark
PRS benchmark · 30 conditions
4 ancestries · 3 cohorts
Conditions where our ensemble model outperformed the published alternative
Scientific Reports, 2025. Trained in UK Biobank; externally validated in eMERGE and PAGE MEC.
55–80×
more true coronary artery disease cases identified by our polygenic score than by rare-variant tests.
~190,000
participants of African, East Asian, European and South Asian ancestry across UK Biobank, eMERGE and PAGE MEC.
Beyond DNA
Genetics shows what your customers are prone to. Our Lab Test Analyzer shows what is happening in their body now, and our Recommendations Engine tells them what to do about it.
Reads blood-test results alongside each person's genetics, so a lab value is interpreted in the context of their genetic risk, and tracks it over time.
4,000+ lab biomarkers supported
Trends over time, with before-and-after for your programs
Interpreted alongside genetic risk, not in isolation
Ranks 20,000+ diet, lifestyle and supplement interventions for each person, using their genetics, lab results, symptoms and goals, and maps them to your products or protocols.
Built from human trials, written by our scientists, not generated by AI
Mapped to your own catalog, products or protocols
Included in reports and available through the API
Published research
Peer-reviewed and open access. Links go to the published versions.
Scientific Reports · 2025
Ensemble PRS models for 30 conditions, validated in four ancestry groups and two external cohorts.
Read the paper →Nature Communications · 2025
Orchestra, our local-ancestry method, trained on 10,000+ individuals from 35 populations and benchmarked against other tools.
Read the paper →Scientific Reports · 2026
Our imputation method, more accurate than Beagle 5.4, IMPUTE5 and Minimac4 on the 1000 Genomes Project and TOPMed datasets.
Read the paper →The team
PhDs, MDs and engineers from the Broad Institute, IBM, Bell Labs and leading universities. Hover or tab through to meet them.
Leadership
15+ years researching health and science. Founded SelfHacked, LabTestAnalyzer and SelfDecode after resolving his own chronic health issues with a gene-based approach.
LinkedIn
Physician-scientist with 15+ years in R&D. Has helped develop 10+ precision medicine products, with peer-reviewed publications and regulatory filings.
LinkedIn
20+ years of C-level experience in technology, healthcare and e-commerce. Took a company from startup to IPO in six years; began his career at AT&T Bell Laboratories.
LinkedIn
30+ years in academia and industry, including IBM and Philips. Joined the Broad Institute in 2003 and created the Trinity RNA-seq assembler.
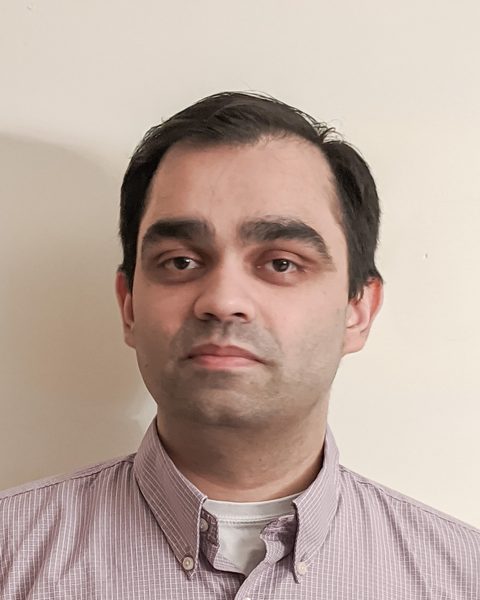
7+ years as a CTO and software engineer, with expertise in natural language processing and data and ML operations.
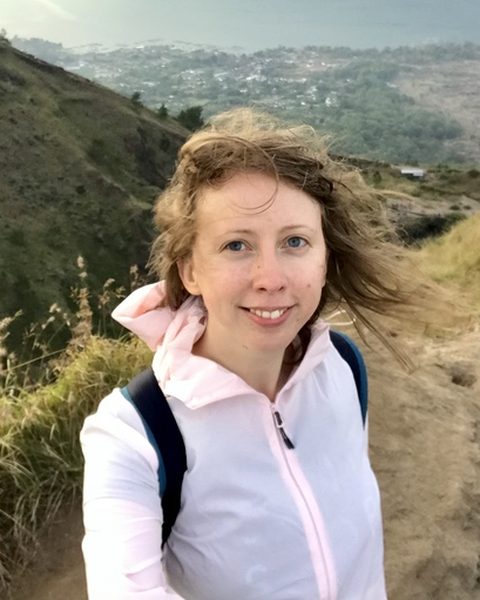
10+ years in life-sciences R&D. M.Sc. and Ph.D. in genetics from a leading Japanese university, specializing in population genetics.
LinkedInScience & engineering leads
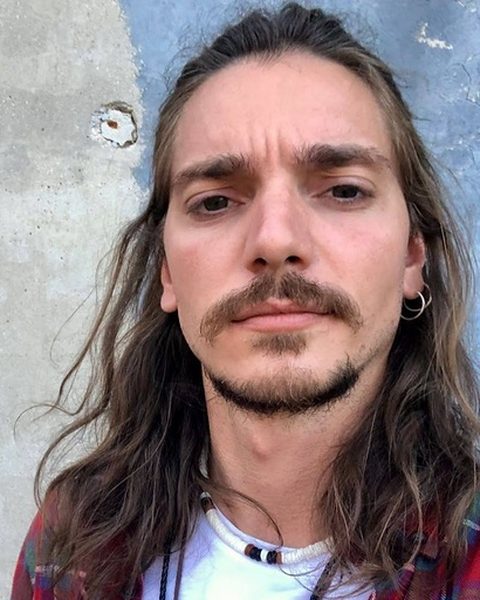
Ph.D. in computer science and M.Sc. in bioinformatics. Lead author of Selphi, our published imputation method.
LinkedIn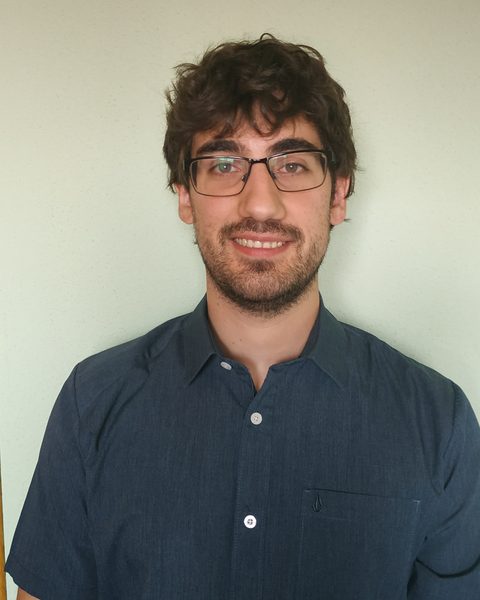
Ph.D. in genetics. Lead author of our multi-ancestry PRS and local-ancestry papers; previously built ancestry algorithms at tellmeGen.
Senior bioinformatics engineer leading research and development on our genomics pipelines.
13+ years in software engineering, formerly with Canon and CTO of Eniplex. Focuses on combining AI with genomics.
Ph.D. in mathematics from the University of Warwick; 10+ years in statistics, modeling and AI, including Deutsche Bank and the NHS.
Software architect and team lead for the platform our partners build on.
Expert bioinformatics
Partners work directly with our genomics team, not just a sales rep.
Validation data, methods and papers for your clinical, scientific or regulatory review.
Your own algorithms on our pipeline, custom reports, or analysis of your own sequencing data.
A named account manager and a shared Slack channel with our developers from day one.
30 minutes with our team, including the papers and validation data.